1
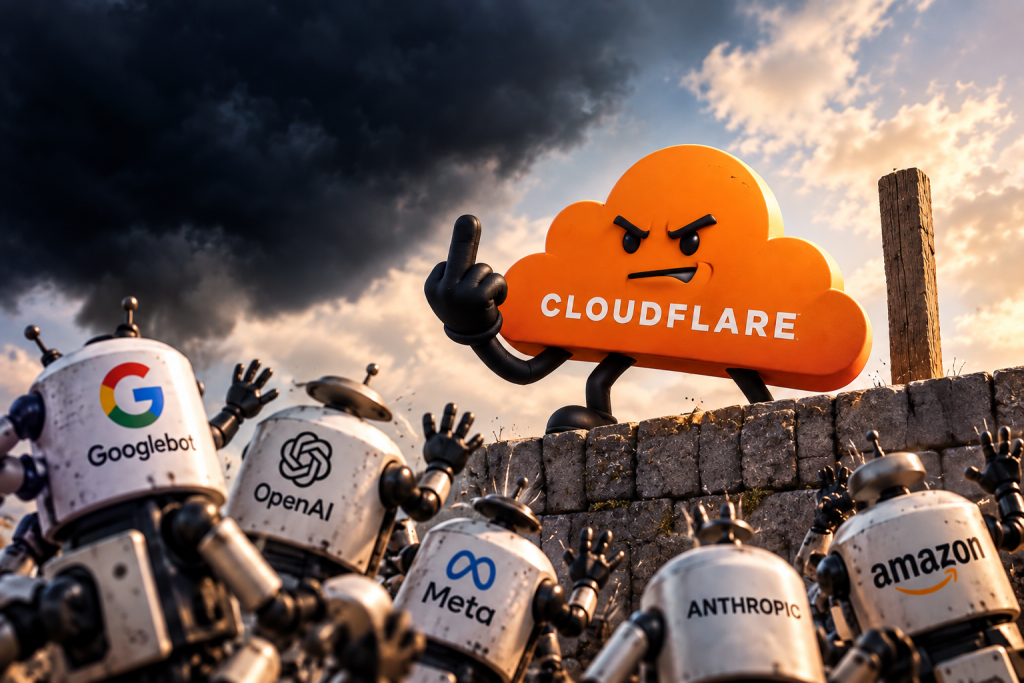
If you run a website, you probably want Google to crawl it. You probably don’t want every AI company on the planet helping itself to your content to train its models.
Until now, separating those two things hasn’t always been easy. Cloudflare is trying to fix that.
On September 15, Cloudflare launched a new Disallow AI Training setting that lets website owners continue welcoming traditional search crawlers while telling AI training crawlers to stay away.
And this isn’t just a polite request.
Cloudflare says training-only crawlers from companies including Amazon, Anthropic, Meta and OpenAI can be blocked outright, while mixed-use crawlers such as Googlebot can still crawl the site for search. Google already lets publishers restrict certain Gemini training and grounding uses through Google-Extended without affecting their Google Search ranking or inclusion.
Cloudflare is going even further with new ad-supported sites. Its recommended settings now essentially say: let search engines in, block AI training, and block AI agents on pages where ads are detected.
There are limitations. Robots.txt ultimately relies on bots behaving themselves, and blocking Google-Extended does notremove your content from Google’s AI Overviews or AI Mode. Those are considered part of Google Search.
But the bigger message is pretty clear.
For years, websites let bots crawl their content because there was something in return: traffic. AI threatens to rewrite that deal by consuming content without necessarily sending the visitor back.
Cloudflare is giving publishers a simple response:
Keep the search traffic. Give the AI training bots the middle finger.

Google Is Testing a Search Bar That Works Outside Chrome
Google is quietly experimenting with a strange new version of Search: one that doesn’t seem particularly interested in staying inside Chrome. The experiment is known as Everywhere Omnibox, with “Loom” appearing in…
Meta Just Launched an AI That Uses Websites for You. That Could Be a Big Deal for Web Designers
Meta has launched Muse, a personal AI agent that doesn’t just tell you how to do something online. It can actually go and do it. There is an important distinction here:…
The “Pixel Police” are Retired: Why AI Agents are the New Mediators of Web Design
Designers would spend weeks crafting the perfect, pixel-perfect dream in Figma, only to hand it over and see it come back looking like a “close enough” cousin once it hit…
The “100x Developer” Paradox: Is AI “Brain Fry” Killing the Craft?
The “10x Developer” used to be a myth—a legendary creature who could out-code a whole team through sheer brilliance and an unhealthy amount of caffeine. Then came Large Language Models…
10 Ways to Build Radical TRUST in the Age of AI Junk
We have reached the era of the “Instant Website.” You can now whisper a few sentences into a chatbot, wait for your instant coffee to dissolve, and watch a fully…

The Great Replatforming: WordPress Is Training Its Own Replacement
For twenty years, WordPress empowered millions of people to build websites. It lowered the barrier, democratized publishing, and quietly created an entire economy of designers, developers, freelancers, and agencies who…